Diagnosis, remediation and data-recovery acceptance are separate stages. This guide does not direct service restarts, queue/state deletion, snapshot cleanup, disabling certificate validation or production restore; validate actual causes against the installed release and the correct run evidence.
Screenshots were captured from the actual lab interface on 16 October 2026. The interface is in English; explanations follow your selected language. Resource names, dates and settings are examples; use values for your own environment.
Some lab screenshots are withheld pending privacy review. Follow the documented steps and use your own environment values.
Visual/action limit: real error screens from the earlier authorized inspection are reused; no new fault was generated and no live logs were collected. Screens do not establish root cause or successful fixes. Commands are read-only examples for the operator to assess on the correct node/service; they were not executed in this inspection.
Platform/release and source/destination identity
Job/run/backup identity and time range
Relevant node, service and evidence source
Redacted support summary and isolated acceptance plan
01
1. Record symptoms and affected scope
Record platform, installed release, source/destination, policy/job/run/backup identities and first failure time. Distinguish creation, discovery, backup, catalog and restore phases. Record unaffected jobs and the last accepted recovery point; do not start production backup/restore to reproduce an error.
Expected result
Record the finding, time and relevant job identity.
02
2. Separate visible errors from connectivity evidence
Network connection error, read timeout and Connection refused are different symptoms, not root causes by themselves. Check source service, endpoint/port, DNS, network, TLS and identity permissions with the responsible owner. The error in the earlier real Windows agent screen is not a valid-connection example. Do not hide failures by disabling TLS verification.
Earlier real Windows Agent Policy error: A network connection error occurred. Source access was not verified and the policy was not saved. This screen does not establish root cause.
Expected result
Record the finding, time and relevant job identity.
03
3. Check service and repository health separately
Verify the installed service name on the relevant node and read status/recent journal entries. A healthy localhost repository backend does not prove the client HTTPS path works. Check mounts, quotas and reservable capacity separately. The example is read-only; restarting or changing configuration is not part of this diagnostic step.
Command example
systemctl status era-repository --no-pager
journalctl -u era-repository -n 100 --no-pager
Expected result
Record the finding, time and relevant job identity.
04
4. Assess misleading capacity errors and empty inventory
The local incident document traced repository capacity preflight failed to clients receiving the wrong 19449 endpoint rather than a full disk. Separate actual mounts from HTTPS /repository access; do not expose 19449 externally. No Instances/VMs, empty Clients or Not Yet Backup are not successful protection; inspect scope, permissions and missing sources.
Expected result
Record the finding, time and relevant job identity.
05
5. Check catalog, chains and the destination UI
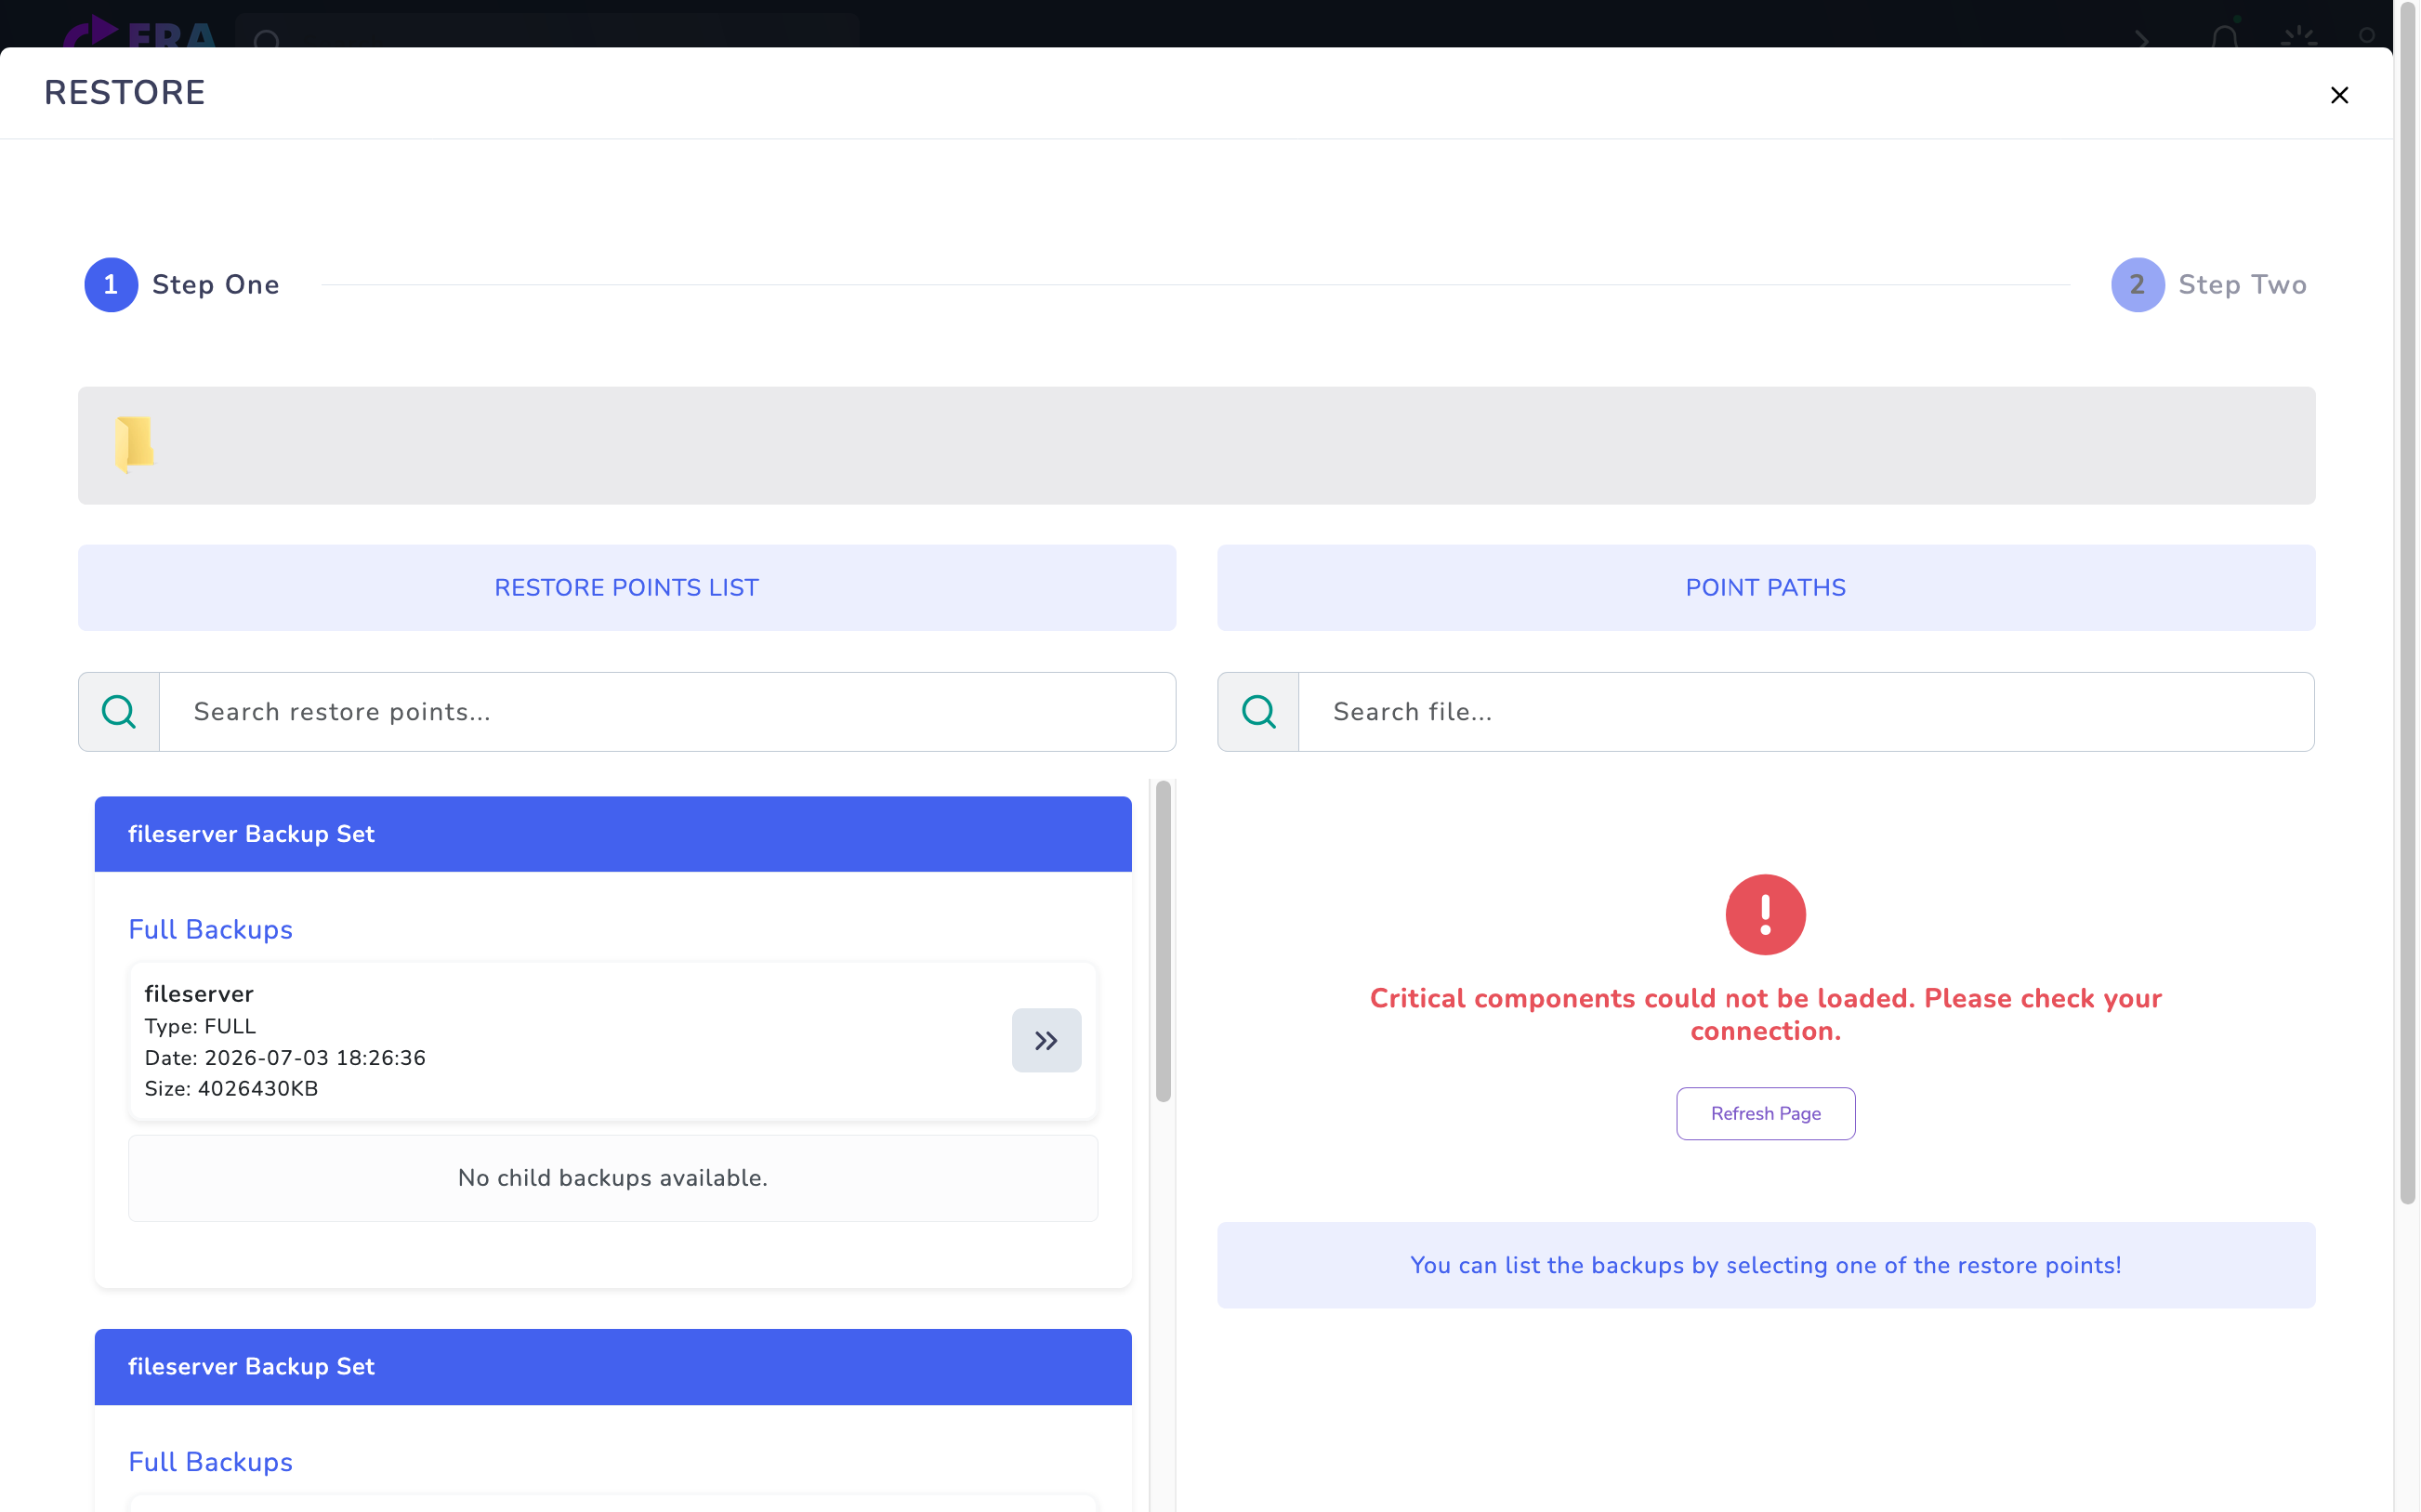
A historical Last Backup date does not guarantee a usable file/VM/database chain. Match the Full base and required logs/incrementals. Critical components could not be loaded indicates a client-component loading issue; it does not by itself prove repository corruption. Stop before final Restore if the tree/destination form has not loaded.
Earlier real fileserver restore screen: Critical components could not be loaded. File tree/target were not verified; Restore was not submitted. A client-component error is not automatic evidence of data loss/corruption. Enlarge ↗
Expected result
Record the finding, time and relevant job identity.
06
6. Assess stuck jobs and cleanup state using evidence
Compare queue, notification, running processes and lifecycle state for the same run. The VMware replication document may retain a failed run’s snapshot and mark cleanup_required; do not manually delete snapshots/state/catalog files. Kill, suspend, restart and retry may affect the data path; apply fixes through an approved plan with the responsible technical team.
Expected result
Record the finding, time and relevant job identity.
07
7. Close the issue with a small test and support record
After an approved fix, validate the same phase and actual data acceptance using a small isolated test. Record before/after findings, identities, release, changes and rollback plan. Redact support logs and share only the relevant time window. No service/task or configuration changes were performed while preparing this guide.
Expected result
Record the finding, time and relevant job identity.
COMMON QUESTIONS
Is an error message itself the root cause?
No. The same message may result from different access, source or data-path problems. Assess time, run identity, services and data state together.